Motivation
So the task is simple (ofcourse for humans only yet) - to fold a 15x15 origami Tant paper to a paper airplane. A lot more challenging for a robot given the multi-modal observation dependency, precise manipulation requirements, a lot of occlusion, and contact rich nature of this task. Clearly visible from the videos above ( teleop vs what our best policy could run).
Problem setup
We were provided Sharpa wave teleop data (550+ episodes of 3-4 mins each) for the competition-set. Modalities include RGB-Head-Left/Right, Wrist-Left/Right, tactile(fxfyfzTxTyTz), joint-torques, tactile-images(raw+deformation). Action were 65 dim vectors corresponding to the 65 robot joints. No simulation available.
Dataset: huggingface.co/datasets/SharpaIT/Robotic_Origami_Challenge
Things we tried:
We mainly experimented the capabilities and limitations of existing works name ViTacFormer - roboverseorg.github.io/ViTacFormerPage and T-Rex - tactile-reactive-dexterous.github.io robotics policies over this task of folding a origami paper using sharpa robot.
We also did some modifications to the existing architecture in hopes of improving it, including:
- Handling degenerate action dimensions.
- Experimented with different actions prediction techniques as mentioned in this paper - (relative vs anchored delta actions, absolute actions, hybrid, )
- Found possible flaws in existing architectures ( shortcut learning in ViTacFormer).
- Stage + progress prediction prediction
- Segmentation + Bbx predictoin
One thing to note is the our validations before testing on real robot were done by measuring deviation from actual teleop runs from the validation datasets. Thus doesn't reflect the capability of the trained model but given we didn't have any actual robot / paper folding simulation this was our only resort to decide which policy to submit for testing phase.
1. ViTacFormer
This was the first policy we adapted to the origami task given it had already worked with sharpa robot albeit on different tasks.
In brief vitacformer itself adpats the pi0 policy to work with extra inputs of tactile. It does this by doing a cross attention between tokens of different modalities. They also used scheduled sampling https://arxiv.org/abs/1506.03099 for tactile predictions( basically use GT for intial phase (~75% of training) until the predictor is trained enough to then use it's predictions.)
Limitations we found: It lacks any language encoder hence lacks the ability to incorporate any task prior using language.
Possible flaws in plain architecture:
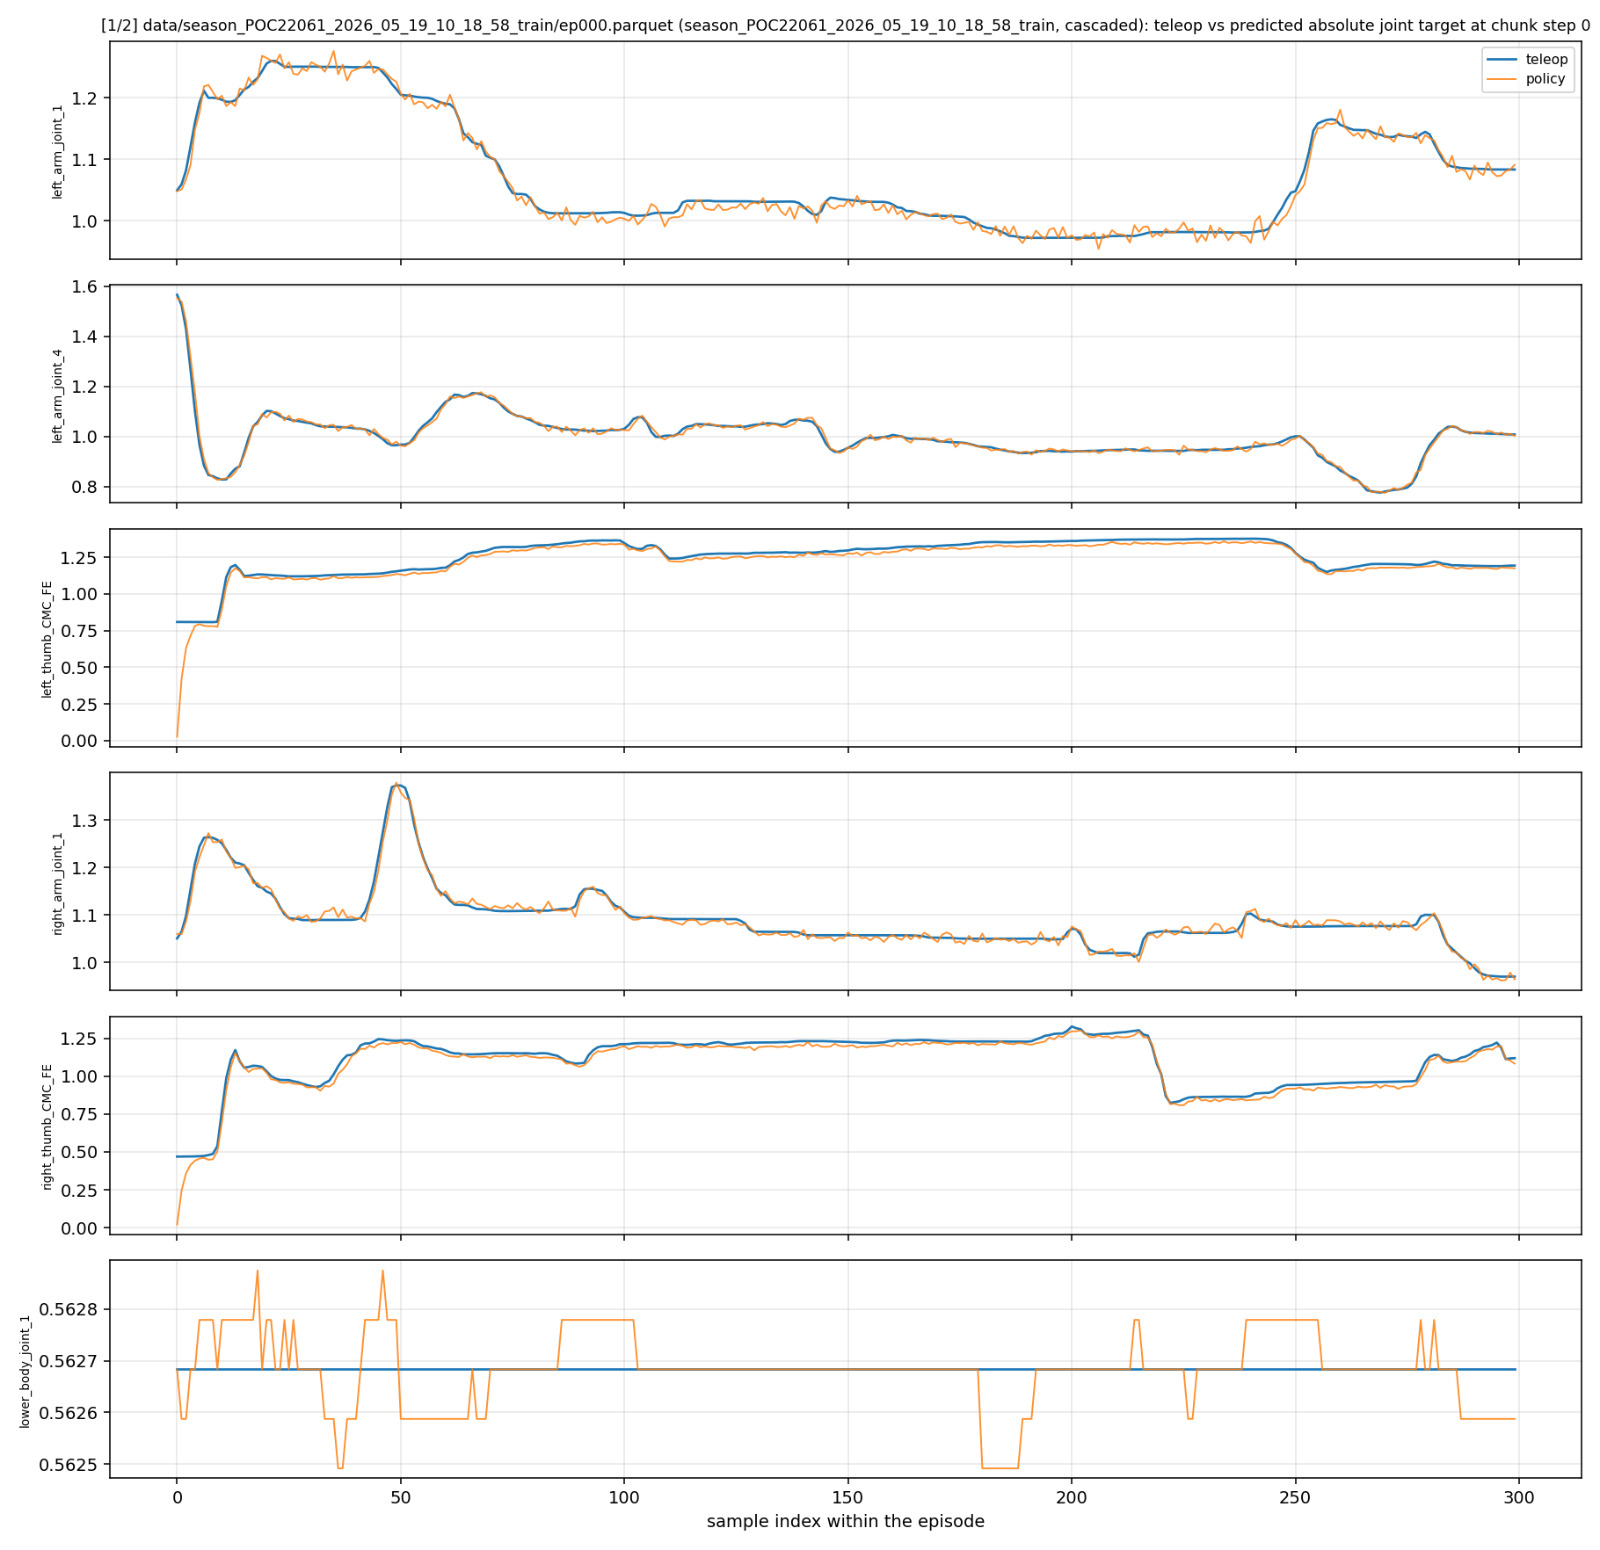
- When current state is passed as one of the inputs it clearly performs shortcut learning, or more formally showcases what is known as causal-confusion where the cause of predicted actions is incorrectly deduced from the input actions. Thus is clearly evident in the plots + video below where the policy we tested on real robot clearly does perform paper folding actions even when the paper is not even grasped. Thus associating current state to next state disregarding image modality. We were excited to see the predicts close to ground truth ( which we were also skeptical of) until we saw the real-robot run on - DATE?
This was also evidient in the ablation we did of trained ViTacFormer.Adding large noise in state affects the output MSE by over 400% while noising image only affects by 4% eventho the tokens pertaining to visual domain are lotmore than state tokens.
TO ADD: OUR SUBMISSION VIDEOS + PLOTS + ABLATIONS.
We also moved on to T-Rex which we found in last week of August over ViTacFormer given better encoders and overall architecture.
2. T-Rex
Tested on Sharpa robot again, T-Rex is a flow-matching based policy that uses slow KV-cache(involving vision + text tokens) to be attended over by fast queries(of actions/tactiles).
Recent papers like [ list of pprs ]. have moved on to flow-matching approaches given the following benfits of 1. Handling multimodalities in actions (as normal MSE is mean seeking( minimizer of mse loss is the mean of the samples) So unlike regression, flow matching estimates the velocityfield at given time step to steer current distribution to the desired distribution.
2. There is definite still MSE loss involved but that is over the velocity field and not that target distribution which prevents average. Also sampling is possible now given the distribution is estimated and not th exact values.
3. Flow matching is prefered over Diffusion (which is a special case of FM), due to shorter probability paths (p1 -> p0).(TO ADD MORE ON THIS) This speed helps in robotic tasks. It was honestly a bit late by the time we started experimenting with T-Rex (already a week into Sept).
Our base policy predicted absolute position we We also tried reducing the noise in predictions due to the flow matching approach by sampling 8 trajectories at a time. But We did try working in EE-space rather than the joint angle space for the robot arms but there were some bugs in pipeline which didn't result it converging properly. and due to time constraints we weren't able to checks it results. and even if it improved I dont think it could have improved the incomplete-folds problem we faced in our best run. We tried Incorporating temporal attention in non-linear window as a proxy for short-term memory (with the intention to handle occlusion and capture progress). But this run gave poorer results ( ig partly because of the improper memory postistional encoding + redundant tokens in kv cache(tho they were masked)) But also the fact that it never ran on the actual robot as the infer call exceeded the time for infer to return. My goal was similar to how RAFT (Teed & Deng, 2020) did a lookup only on neighbourhood in the whole correlation volume, but we do this in attention computation. Thus, add an inductive bias to the model to look up temporal frames only in the neighbourhood...this would have saved a lot of unnecessary model updates.
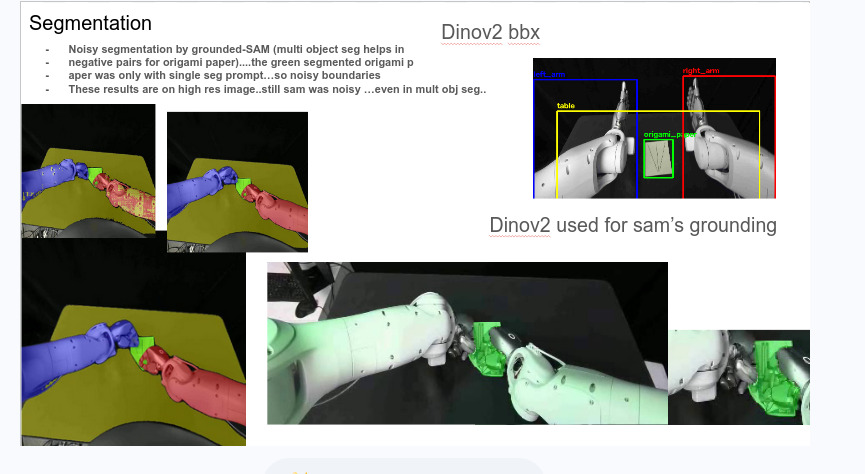
We also tested SAM for Segmentation but the masks were unreliable. So we skpipped.
Object Detection and Segmentation Pipeline
Stage label and progres annotation
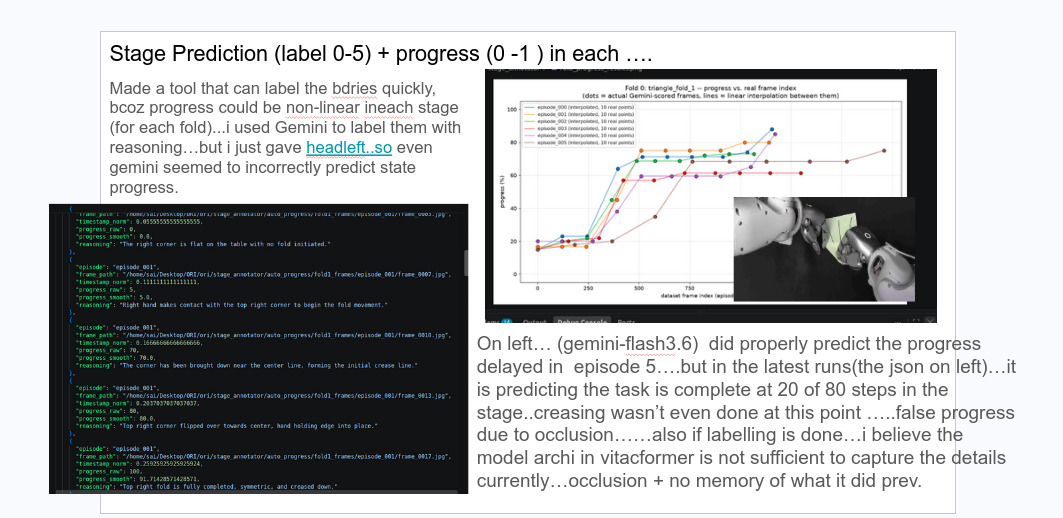
Stage labelling should have improved inference, but there 3 problems with This 1. Labelling the data: I manually tried labelling the boundariews of each episode.( created a tool that saves the time stamps on pressing a key). Though it was tiresome (30sec for each epi, 500+ episodes) it was doale if problems 2, 3 didn't exist. 2. For withing stage progress we thought of either (temporal interpolation with noise) or just use VLM to lable progress ( we tried Gemmini Flash+ some models using nematron api)..and they were terrible. 3. Even if all of above worked, there was a concern that if the robot goes into a failure mode(which we observed while it pressed onto the paper to grab it from another hand), that actions/scenes it will do/observe will be very different from training, so the stage+progress will be way off and might instead hurt the policy. Given the time required for labelling we didn't go ahead with this method.
Final Run in IROS conference (based on we got the scores)
Results
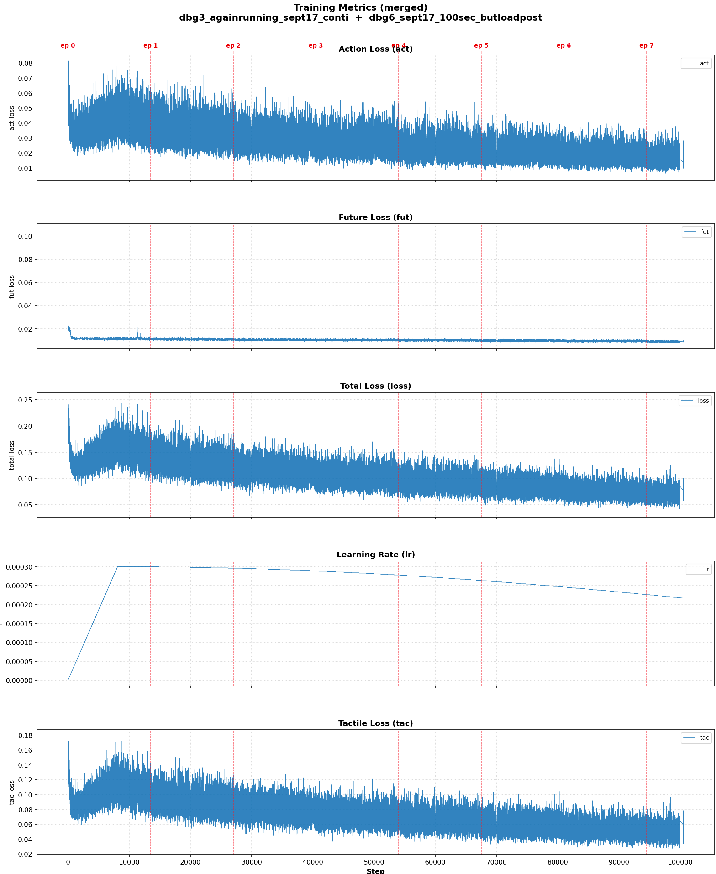
numbers / plots show.
Conclusion
REPLACE ME: what worked, what the takeaway is.
Observations & Mistakes
- We should have tried to fit the outputs of the policy with splines to get smooth motion control(upto an order). A clear jerky motion is visible in our outputs. That is possibly due to uncertainty in model prediction and loss of continuity from previous predictions.(as we dont give current pose in input to avoid causal-confusion).
- ...
Future plans
- Develop our own paper simulator.(There's apparently no qualtiy paper simulator+manipulator for paper folding which works on GPU)
- Train a policy in simulator first.